Key Takeaways
- A benchmark tells you whether there’s smoke. Your own accounts, tickets, teams, tags, and comments help you find the fire. For IT service and MSP teams, use relevant IT-service benchmarks for the outside comparison and those internal records to explain the gap.
- A single average can hide a lot of daylight between providers, and one survey wave can’t show direction. Look at the spread inside the sector and the trend over time before you decide what the gap means.
- When the question and scale stay the same, you can reliably compare service results.
- Same label, different math: A 4.5/5 average, an 85% positive-response score, and an index score don’t tell you the same thing. Match the benchmark to the way your own CSAT is calculated before you compare results.
Two numbers can both say “CSAT” but measure different things. An overall-provider survey, a post-ticket score, complaint feedback, and a five-point contact-center average don’t belong on the same scoreboard just because the label matches.
Industry and service benchmarks give you the broad view. To find the comparison that actually fits your program, match how the score was calculated and what customers were rating first. Then narrow by customer group, market, time period, and how the benchmark grouped and combined the responses. Provider ranges show how far results can vary inside one sector, while repeated surveys reveal if satisfaction is moving. Once you’re in the right neighborhood, your own accounts, teams, tickets, tags, and comments can pinpoint where the gap is coming from.
What are the current CSAT benchmarks by industry?
CSAT benchmarks look very different depending on what the surveys measure. In global customer-service studies, industry results ran from 25% for government agencies to 53% for insurance, with 45% across the full sample and 55% for the U.S. sample. In studies that used the same five-point overall-provider question across seven major services, results ran from 73% for landline service to 88% for mobile and main banking.
Use the first set to compare customer-service satisfaction across industries and the second to compare overall-provider satisfaction across those services. Then narrow further to a benchmark that matches how you calculate CSAT and what customers were rating.
Customer-service satisfaction across industries
Survey data from Capgemini found that customer-service satisfaction (combined “satisfied” and “very satisfied” responses) ranged from 25% for government agencies to 53% for insurance. Banks tied with the full sample at 45%, with consumer products close behind at 44%.
Cross-sector customer-service satisfaction
|
Industry or scope |
Satisfied or very satisfied |
|
Overall |
45% |
|
Insurance |
53% |
|
Banks |
45% |
|
Consumer products |
44% |
|
Travel and hospitality |
39% |
|
Retail |
38% |
|
Automotive |
37% |
|
Telecom |
35% |
|
Utilities |
33% |
|
Government agencies |
25% |
Satisfaction with major services using one survey question
Employing the same five-point question across seven major services, overall-provider satisfaction ranged from 73% for landline service to 88% for mobile and main banking, according to Ofcom. Fixed broadband reached 84%, pay TV 83%, electricity 80%, and gas 79%.
Because every service used the same question, scale, and definition of “satisfied,” you’re able to compare the same measure evenly for all the polled services.
Current-provider satisfaction across major services
|
Service category |
Very or fairly satisfied |
|
Mobile |
88% |
|
Main bank |
88% |
|
Fixed broadband |
84% |
|
Pay TV |
83% |
|
Electricity |
80% |
|
Gas |
79% |
|
Landline |
73% |
The first table gives you customer-service context across industries. The second gives you overall-provider context across seven services measured the same way. To benchmark your own CSAT against either one, match what customers rated and how the score was calculated first.
Match the benchmark to the way your CSAT is measured
Before you compare your CSAT with a benchmark, make sure the scores were built the same way and came from a similar survey. Start with the math: percentage, average, index, or product-specific formula. Then check what customers were rating, who answered, and how the study combined the responses. When those pieces line up, you’re much closer to an apples-to-apples comparison.
Check the math
An 80% positive-response CSAT means 80% of valid responses met the defined “satisfied” threshold, while a 4.5/5 score is the average of every rating. A satisfaction index can combine several questions through its own weighting model. Compare each one with the same kind of score, meaning percentage with percentage, average with average, and an index with the same index model.
Even matching averages can hide different response patterns. Seven fives, two fours, and one two average 4.5/5, but so do five fives and five fours. The first set contains a sharply negative rating, whereas the second is clustered at the top. The average gives you the headline, so you need to look at the individual ratings to see how that 4.5 was built.
To calculate a positive-response percentage, group the ratings that count as satisfied and divide them by all valid responses.
How common satisfaction scores differ
|
Score type |
What the number represents |
Best comparison |
|
Positive-response percentage |
Share of valid responses that reached the satisfied threshold |
Another percentage using the same threshold and survey event |
|
Average rating |
Mean of every response on the scale |
Another average on the same scale |
|
Satisfaction index |
Several weighted questions combined into one score |
The same index across sectors or periods |
|
Product-specific formula |
Score created by the product's own calculation |
Your own past results or another result using that formula |
Match what was surveyed, who answered, and how responses were combined
Once the math lines up, match the experience being rated. An overall-provider survey asks customers to judge the provider across ongoing use. Complaint feedback focuses on how a recent problem was handled, and ticket feedback follows a completed support interaction. A B2B service survey can cover delivery, communication, governance, and trust across the account.
Look at who answered next. Consumers, enterprise buyers, housing tenants, IT users, and managed-service clients have different service relationships. Match the respondent group, market, and survey period to your own program.
Finally, check how the study turns responses into the reported number. Some studies pool every response. Others calculate a score for each provider and report the median provider. Indexes can also weight several questions. A pooled response percentage and a median provider score can both appear as one number, but they summarize the data differently.
Compare providers and track the trend
An industry average gives you one reference point but doesn’t show how much providers vary within the same sector. One survey gives you one frame. Repeated surveys show whether satisfaction is rising, falling, or holding steady. Use both before you decide what your gap to the benchmark means.
Gauge provider satisfaction ranges inside the same sector
According to the UK’s Regulator of Social Housing, low-cost rental satisfaction had a 71.8% median, while low-cost home ownership had a 47.9% median.
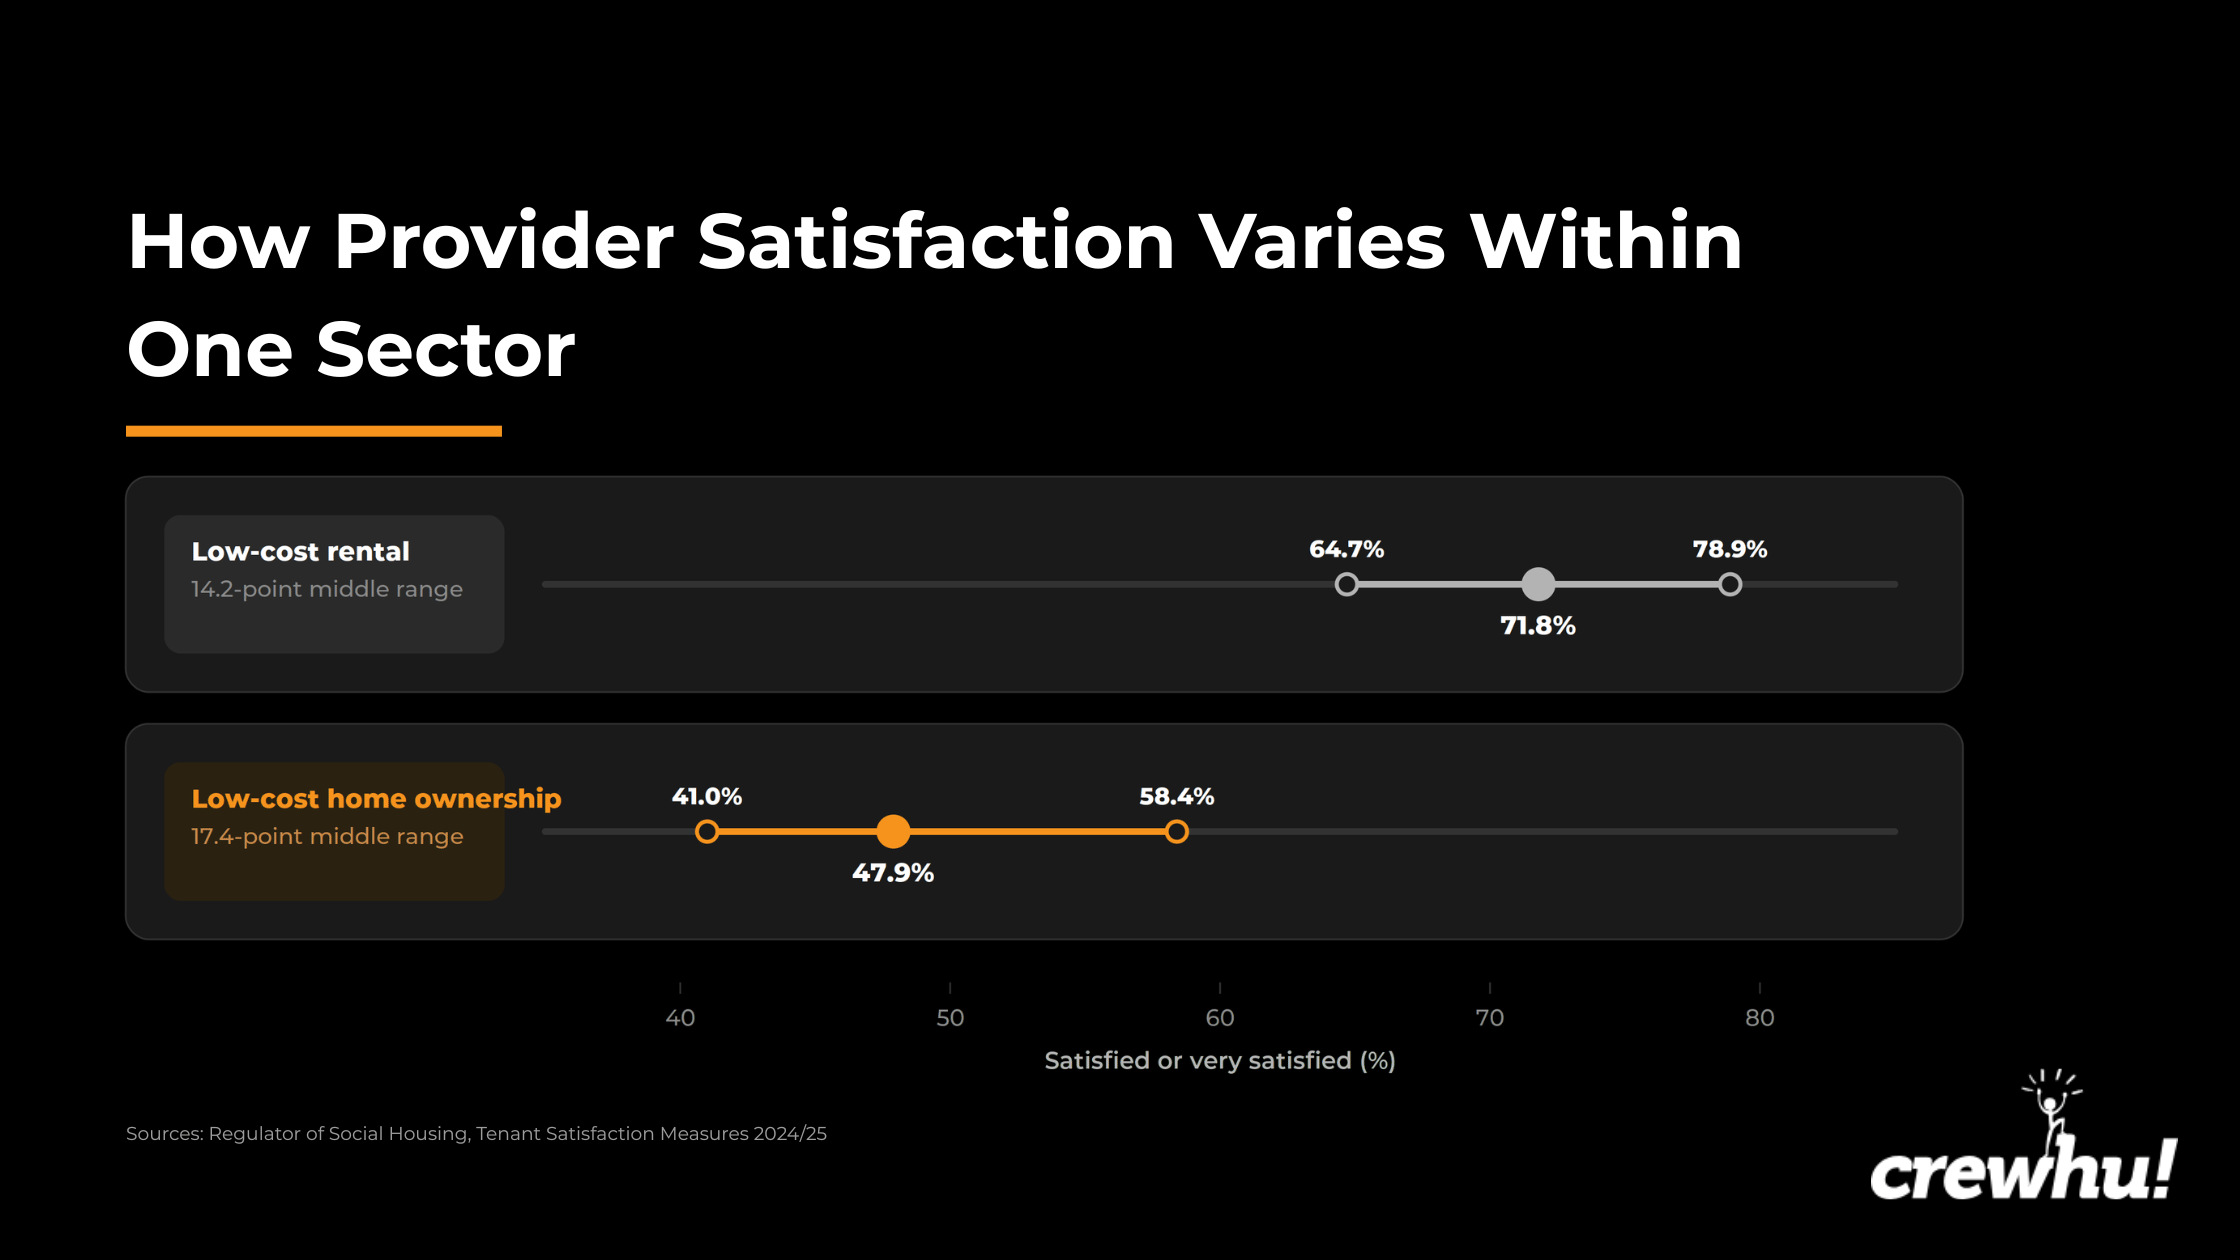 The middle 50% of low-cost rental providers scored from 64.7% to 78.9%. For low-cost home ownership, the middle 50% scored from 41.0% to 58.4%. That shows how much provider scores can differ even within the same sector. A rental score near 70% sits close to the 71.8% median, giving a landlord a comparison built from the same provider type, tenure, question, and reporting period.
Track the same measure over time
Joint research from Ofgem and Citizens Advice found that energy customer-service satisfaction rose from 62% in August and September 2023 to 77% in January 2026 when using the same customer service question. And among customers who had contacted their supplier in the previous three months, satisfaction reached 81%.
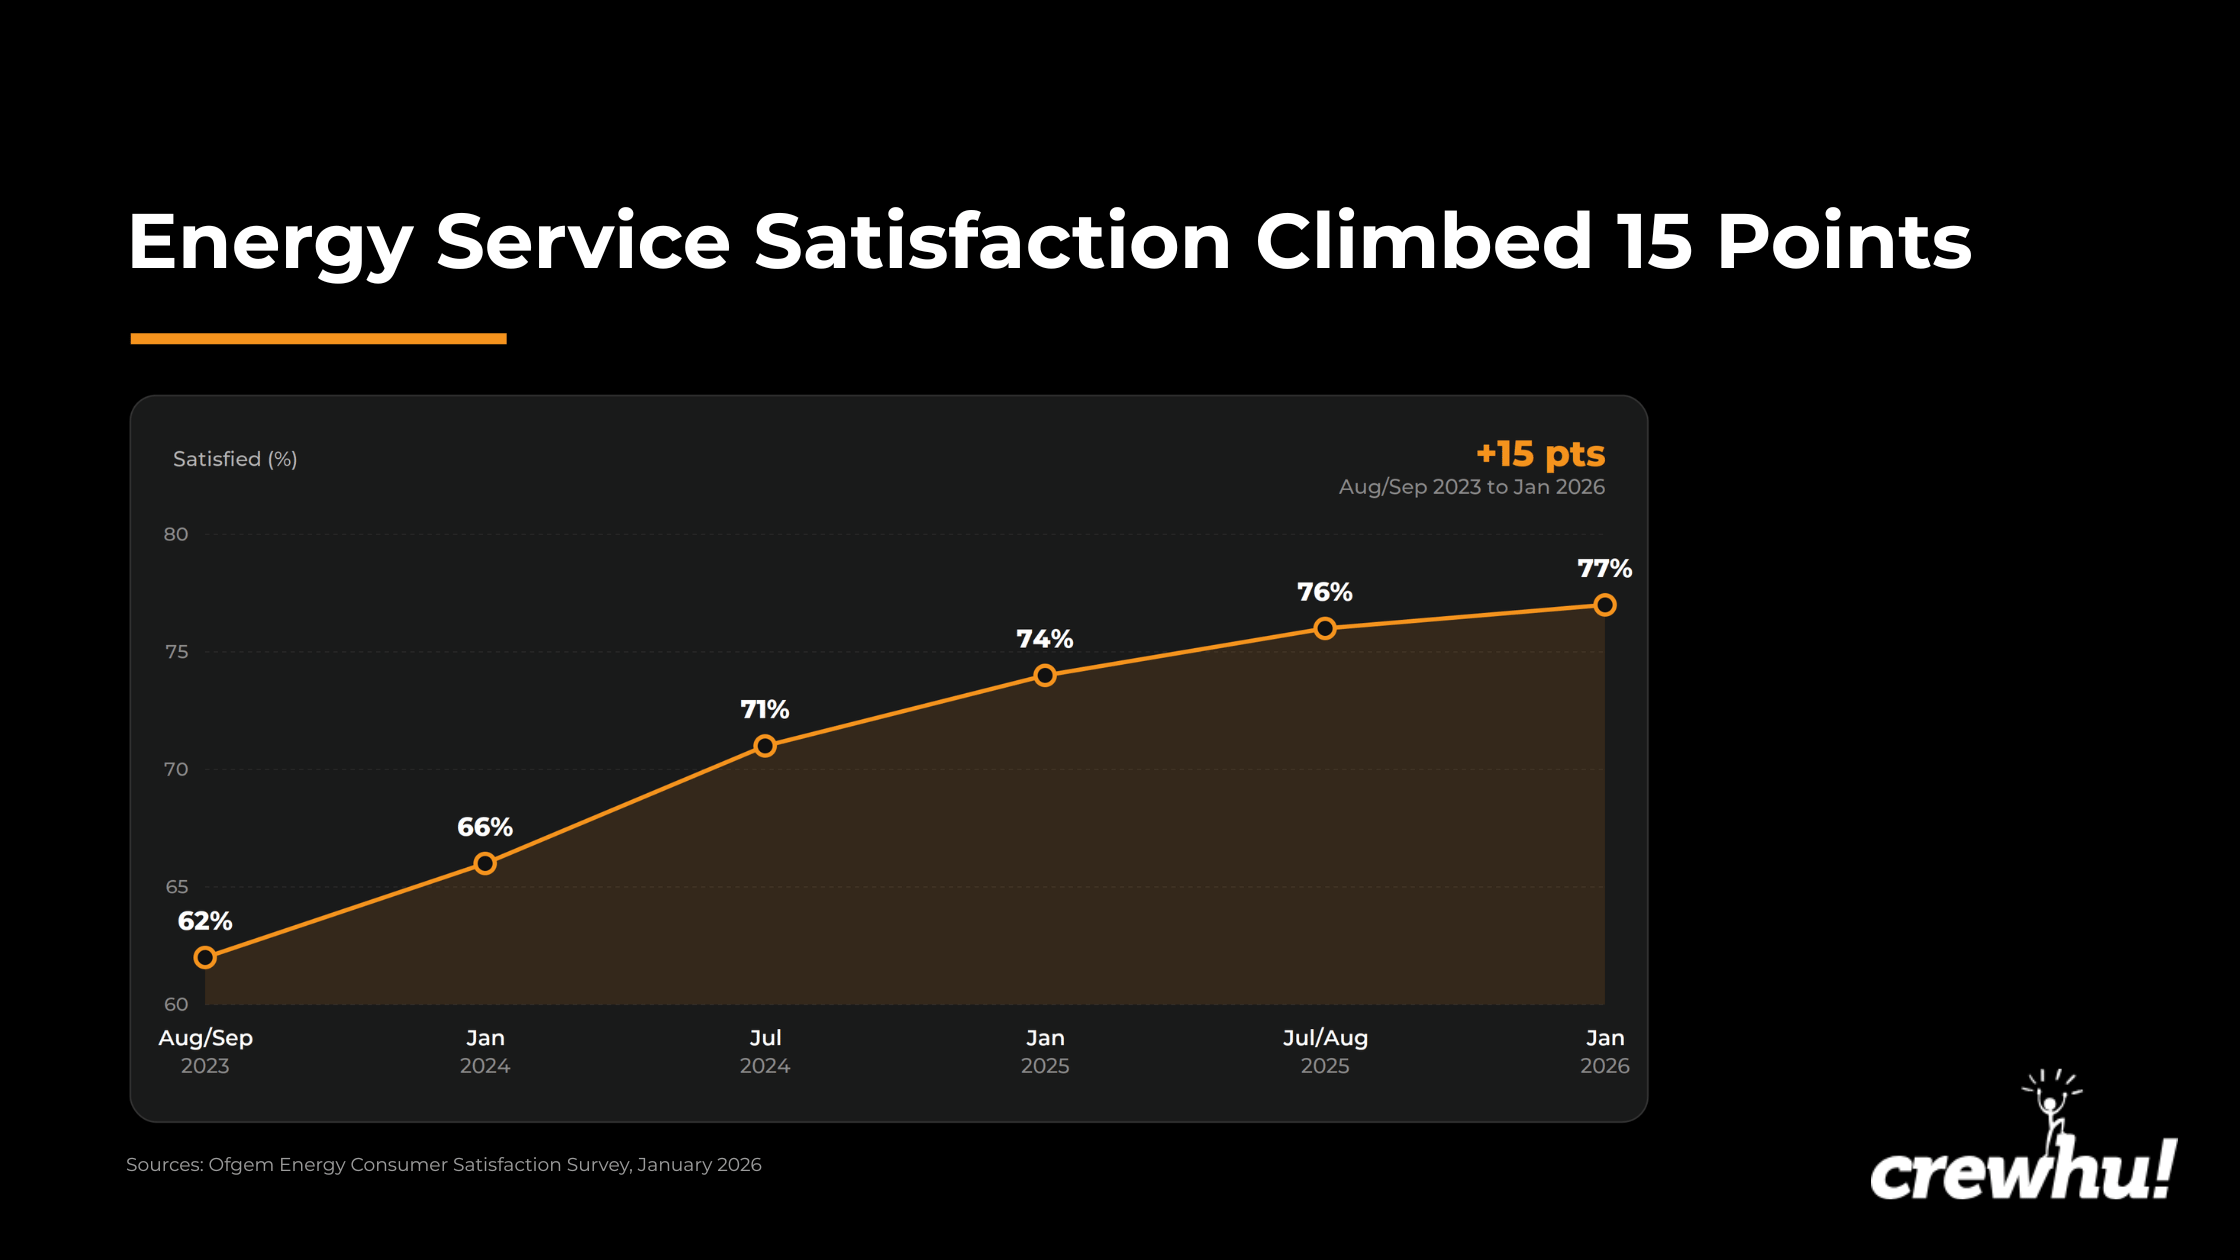 That 81% from recent customers lets service teams hone in on a closer segment of interactions compared to the all-customer score. For your own CSAT, keep the question, scale, survey trigger, and review interval consistent from one period to the next. Then you can see if satisfaction is moving on the same measure.
Benchmarks for complaints, contact centers, and IT services
The closer the benchmark is to the work being rated, the more useful the comparison. Complaint handling, phone support, IT tickets, and ongoing B2B relationships each measure a different part of the service experience, so keep them separate.
Complaint handling and phone support
Among people who had complained to a provider in the previous six months, complaint-handling satisfaction reached 61% for mobile, 60% for landline, and 58% for fixed broadband. The ratings from Ofcom were based on a 10-point scale, and those from 7 to 10 counted as satisfied.
The mobile category shows why the survey trigger matters: Overall-provider satisfaction was 88%, reflecting the consumer’s general relationship with them. Mobile complaint handling’s 61% satisfaction rating highlights how well a recent problem was handled.
Across nearly 3,000 Talkdesk customers, over 712,000,000 calls, four industries, and six continents, the average CSAT for phone interactions was 4.5/5. For benchmarking, businesses would want to pair it with another five-point call CSAT average. The 4.5/5 reveals how callers rated the interaction. Answer speed, waiting time, hold time, and service level show how the call operation performed. If weaker CSAT appears alongside longer waits or holds, those metrics give you a concrete place to investigate.
IT service and managed services
Freshservice reported their overall CSAT reached 97.83% across more than 187 million tickets. For IT teams, that brings the comparison closer to day-to-day service desk work than a broad consumer benchmark.
Regional results also vary by industry. Finance stayed above 95% across the Americas, Europe, and the Asia-Pacific, the Middle East, and Africa, ranging from 95.48% to 99.33%. Media/internet varied more, from 89.45% in the Americas to 96.63% in the Asia-Pacific, Middle East, and Africa.
|
Industry |
Americas |
Asia-Pacific, Middle East, and Africa |
Europe |
|
Business services |
98.06% |
97.31% |
98.28% |
|
Construction/Real estate |
98.72% |
95.65% |
98.33% |
|
Consumer products and services |
96.52% |
93.78% |
99.38% |
|
Education |
97.78% |
95.65% |
98.00% |
|
Energy |
97.92% |
95.67% |
96.28% |
|
Finance |
99.33% |
95.48% |
99.12% |
|
Government/nonprofit |
99.02% |
96.63% |
97.13% |
|
Healthcare |
98.32% |
96.04% |
97.38% |
|
Leisure/Hospitality |
98.76% |
94.23% |
96.55% |
|
Logistics and transportation |
98.33% |
96.60% |
96.60% |
|
Manufacturing |
98.15% |
94.00% |
94.76% |
|
Media/Internet |
89.45% |
96.63% |
92.60% |
|
Retail/eCommerce |
100.00% |
97.82% |
96.47% |
|
Software |
98.85% |
95.05% |
96.43% |
Enterprise service-provider research adds the account-level view. ISG’s Q2 2025 CX Insights discovered that more than 70% of enterprises were satisfied with providers’ adherence to policies and regulations. Collaboration was stronger, with nearly 90% satisfied or highly satisfied, while almost two-thirds were only moderately satisfied with innovation.
The ITO and BPO cuts show where those strengths and weak spots sit. More than 60% in both groups rated provider collaboration highly. Over half were satisfied with execution and delivery, while around 40% remained only moderately satisfied. In BPO, innovation was still rated mostly moderate.
Ticket CSAT tells you how individual support interactions went. Account-level measures show how communication, delivery quality, governance, and innovation are working across the relationship. Recurring B2B services need both views.
For MSPs, pair relevant IT-service benchmarks with your own results by account, ticket type, service line, team, and issue tag.
Build the comparison in three layers:
- Use IT service management data for service-desk operations.
- Use enterprise account data for account health and delivery quality.
- Use your own post-ticket results for day-to-day management.
Each layer answers a different question. When more than one points to the same service issue, that’s where you should investigate first.
How to choose the closest CSAT benchmark
Start with the scoring method and the event that prompted feedback. Then narrow the comparison through customer type, market, survey period, and response coverage. Aligning on calculation and feedback trigger carries more weight than an industry label alone.
Work from the scoring method to the internal evidence needed for action.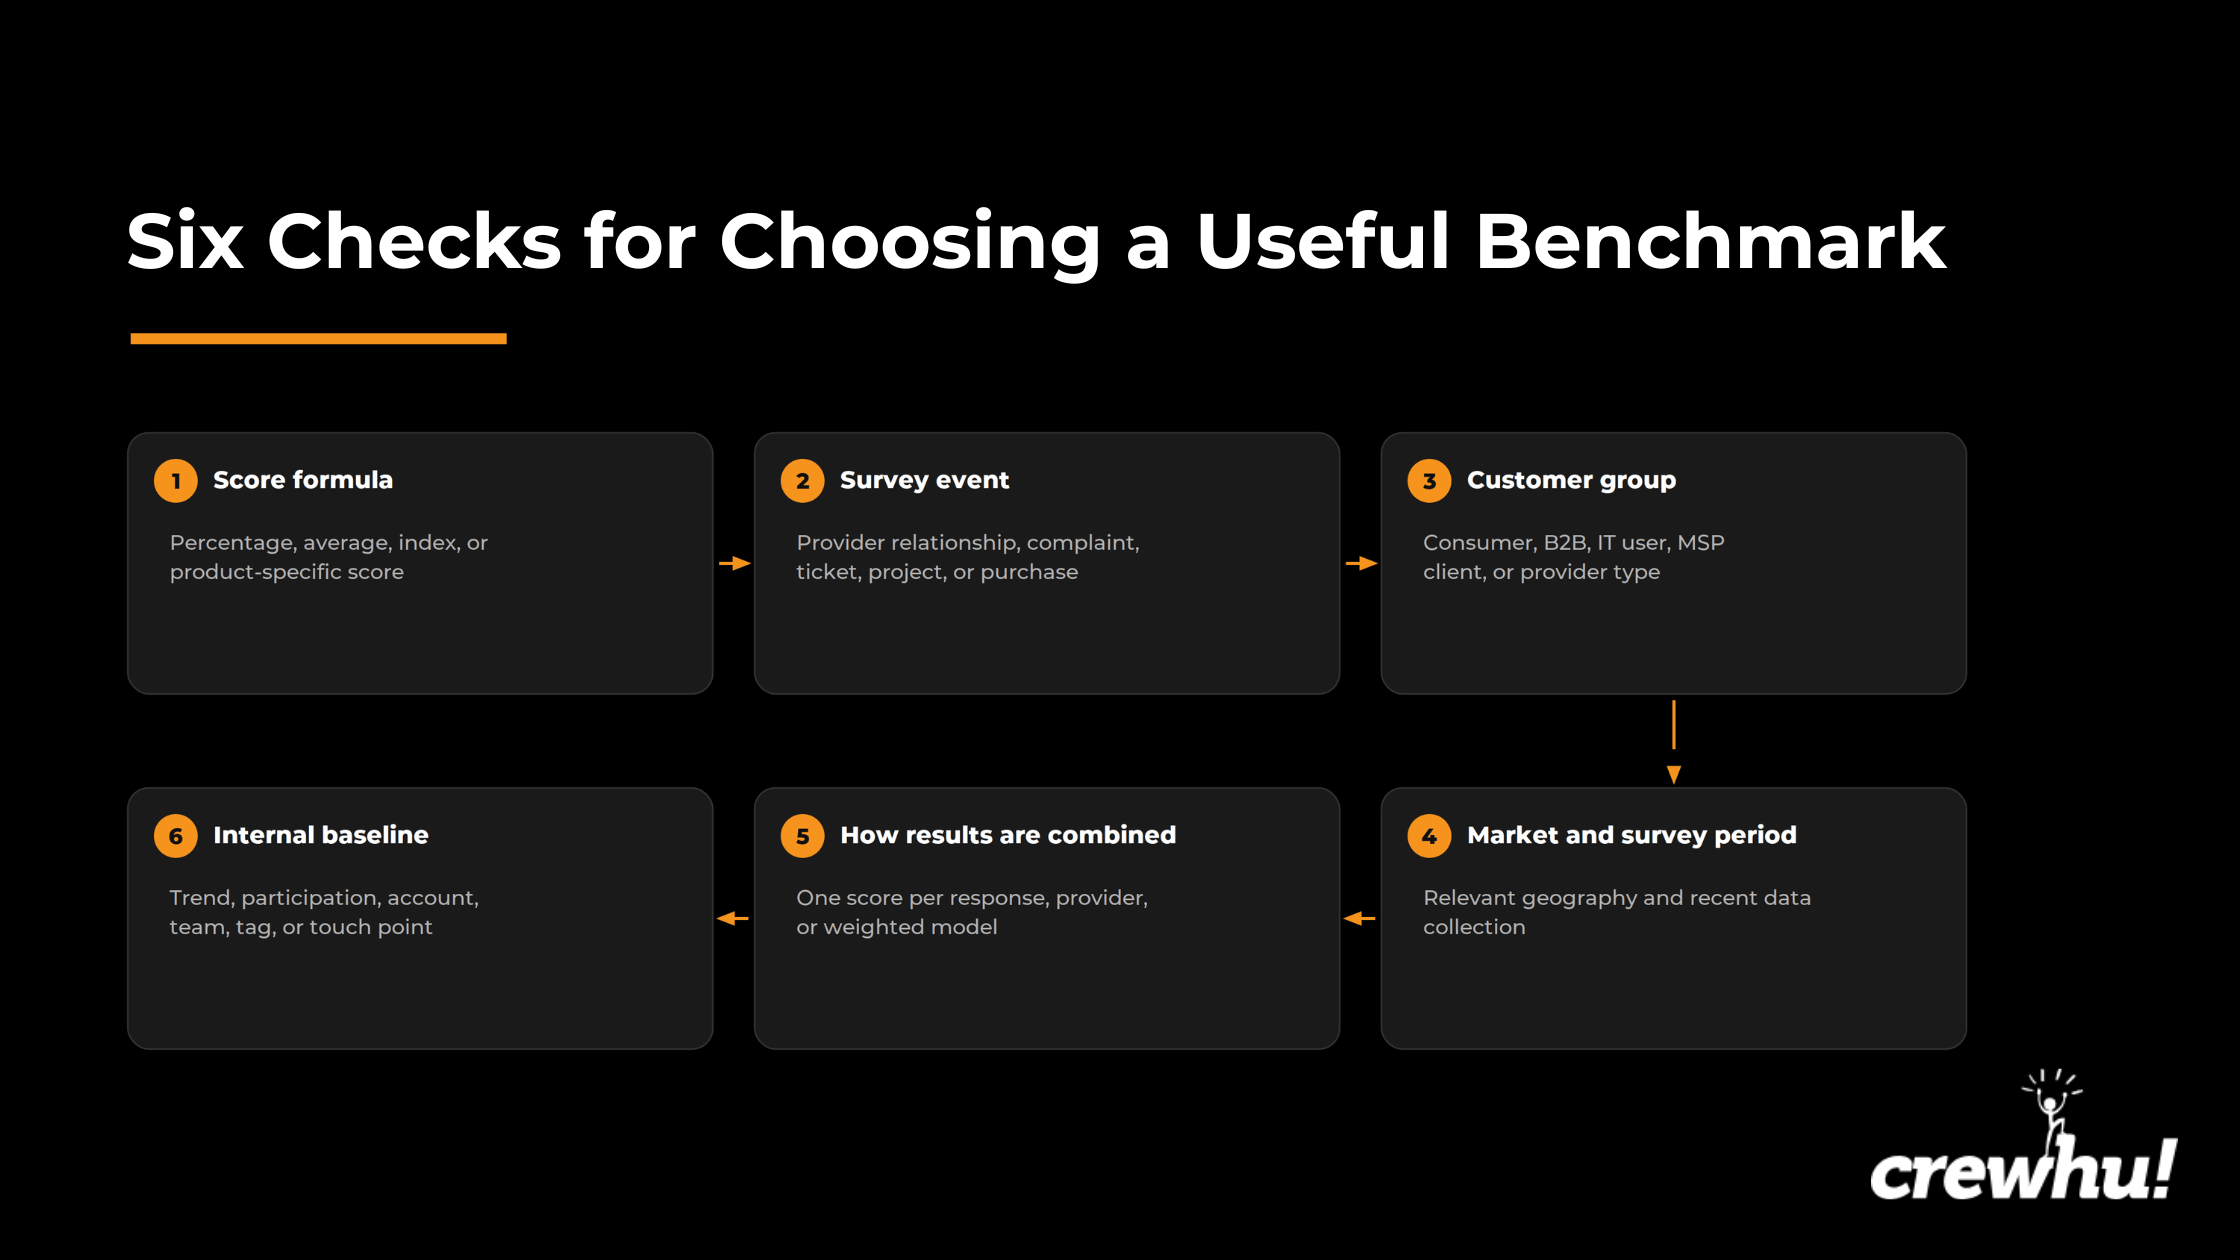 The order of steps matters. Score calculation and survey event come first. Then check how closely the published benchmark matches your customers, market, and service model.
Closest benchmark checklist
|
Check |
A close match |
How to use the result |
|
Score calculation |
Same percentage, average, index, or product formula |
Track each result within the same method |
|
Survey event |
Same type of survey: overall provider, complaint, ticket, project, or purchase |
Choose the event closest to the experience you manage |
|
Customer group |
Similar consumers, business clients, service users, or IT users |
Use the closest clearly defined customer group. If it differs from your customers or service model, give more weight to your own past results. |
|
Market and survey period |
Relevant market and recent data collection |
Use the nearest market. A stable older series still shows direction |
|
How results are combined |
Same response-level, provider-level, or modeled calculation |
Match the type of average or distribution used by the study |
|
Response coverage |
Sample and customer coverage fit the decision |
Read the result beside your response volume, customer coverage, and trend |
In the real world, this looks like:
- A hotel getting its strongest reference from a hospitality study conducted after a stay
- A professional services firm gaining a better understanding from a client survey covering delivery and account management
- An IT support team starting with service desk data and then narrowing the view through its own ticket types and customer accounts
Company size can tighten the match when the source reports separate size groups. For example, Freshservice breaks out response time, resolution time, first-contact resolution, and SLA performance by company size. Use the closest benchmark alongside your internal baseline to set a realistic CSAT target.
Recommended Listen
In episode 257 of the “Customer Support Leaders” podcast, host Charlotte Ward talks with Ty Givens, founder and CEO of CX Collective about customer service and the value of metrics.
Givens argues that an industry benchmark gains meaning when a company reads it through the service it promises and the customers it serves. Ward and Givens then examine the written feedback behind the score. Customer comments reveal expectations, recurring friction, and service details that an aggregate percentage leaves hidden. Those details give teams a stronger basis for setting internal goals and deciding what to change.
What to do when your CSAT differs from the benchmark
An industry benchmark shows where your score sits. Your own data shows what changed and where to look. First check the trend, response volume, and customer coverage. Then break the result down, identify a recurring issue, and give it an owner, a first action, and a review date.
Check the internal trend, participation, and service breakdown
Start with the trend. A one-month drop can reflect a small response count or one concentrated incident. A change that continues across several review periods deserves a closer look.
Use this diagnostic sequence:
- Compare valid responses and participation with earlier periods.
- Check how broadly the responses cover your customer base. A solid response count can still give you a narrowed view if most replies come from only a few accounts.
- Break down the result by team, technician, service line, issue tag, and survey type.
- Read the written comments and related ticket records behind the biggest score gap or drop. See if that change persists across more than one review period. Also note whether response volume or customer coverage changed at the same time.
- Identify the smallest recurring issue that needs an owner.
This process moves the team from a market comparison to a specific service issue an owner can investigate.
Assign the trigger, owner, first action, and review date
A repeatable response needs a defined trigger, one accountable owner, a specific action, and a date for reviewing the result.
That workable trigger could be a segment that falls outside its internal range for two review periods. Choose a first response such as a ticket-sample review, targeted customer follow-up, workflow inspection, or coaching conversation. The review date keeps the action connected to its result.
The first response leads into the complete customer feedback loop, where recovery, follow-up, reinforcement, and organizational learning continue.
Connect the benchmark to the service work behind it
Once a benchmark reveals a gap, look for the account, interaction, team, issue tag, survey type, or response group behind it. Crewhu's good-minus-bad CSAT calculation subtracts the bad share of reviews from the good share, while okay ratings stay in the response base. So, with 16 good, three okay, and one bad response, the CSAT score would be 75. The result keeps positive and negative ratings visible in one number for consistent internal comparison.
Crewhu’s Pulse dashboard then brings the score, response volume, filters, service tags, written feedback, and individual surveys into one view. Teams can trace a broad change to the account, tag, or response behind it and assign follow-up to the right person.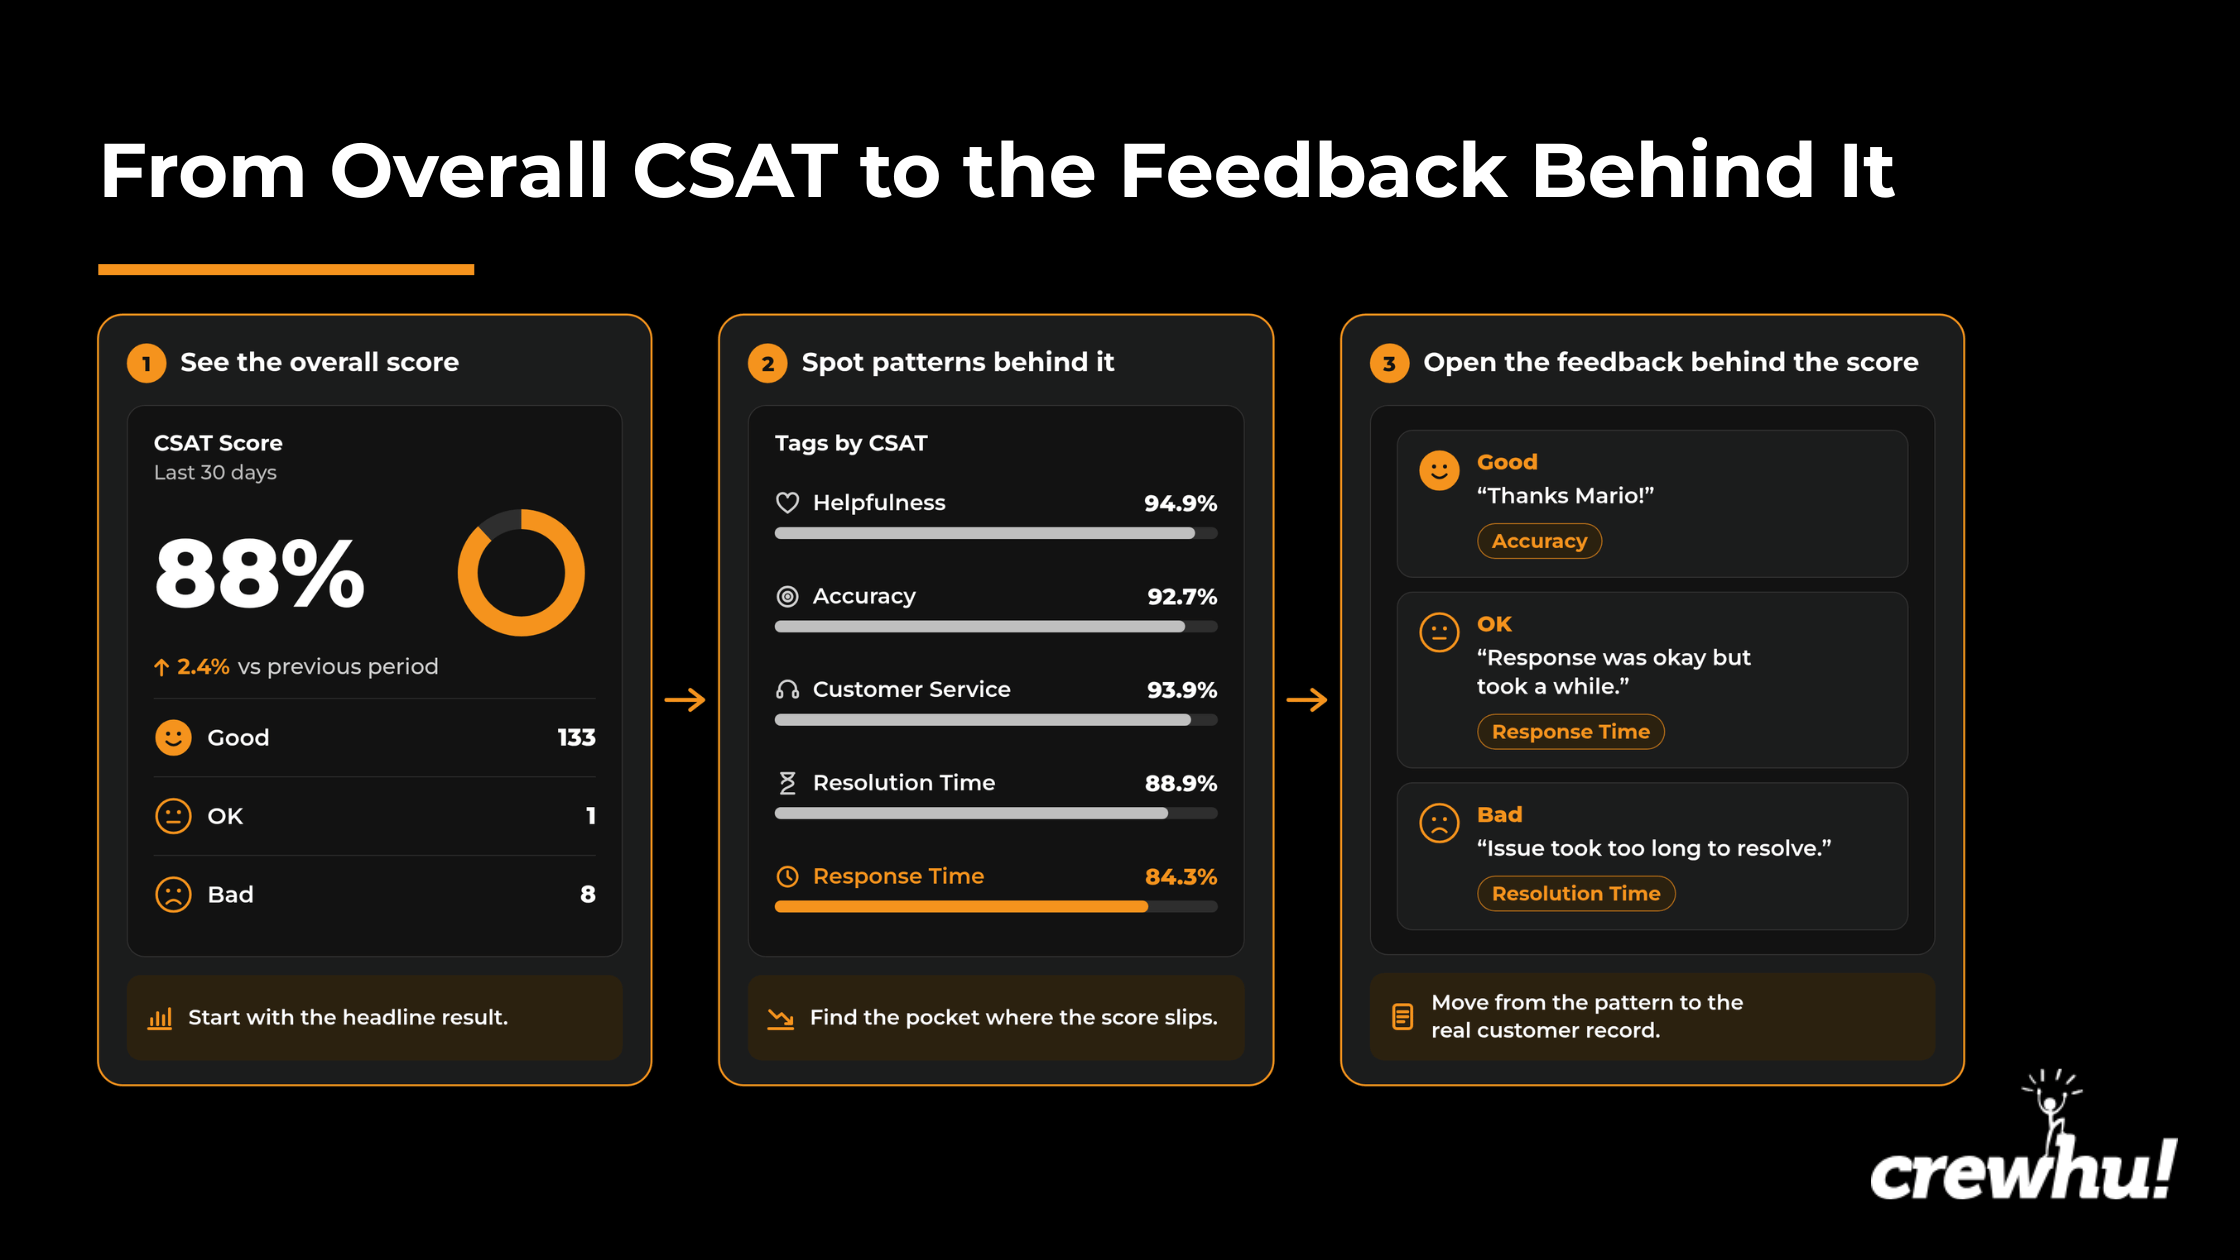 The customer feedback workflow keeps surveys connected to the ticket, project, or service interaction and the people responsible for it. Negative responses prompt follow-up. When the same survey tag keeps appearing across multiple responses, managers can review those cases together to spot a recurring service pattern and decide what needs attention. Positive comments identify behavior worth reinforcing through coaching or recognition.
GO2 Tech experienced this power firsthand: The company was growing across multiple teams, remote staff, and overseas operations but didn’t have a structured client-feedback process. Small issues could slip through, recurring concerns sometimes went unresolved, and employee recognition was inconsistent.
After another MSP recommended Crewhu, GO2 Tech made implementation a priority. The company added Crewhu guidelines to its policy platform and integrated the metrics into performance reviews and year-end awards. The program generated more than 1,300 responses from over 400 people across more than 250 clients, while participation rose 12%. GO2 Tech was able to easily track CSAT in real time and identify trends through survey tags, leading to richer, more meaningful customer interactions.
Compare your score with the closest benchmark
Measure your CSAT against the closest matching benchmark to see where you stand. Your own trends and breakdowns will reveal what needs attention.
Provider ranges show where an organization stands, repeated surveys track direction, and internal breakdowns identify the account, team, tag, or touch point that deserves attention. The benchmark is meant to change a service decision and give it a clear owner.
Keep your benchmarks and feedback in the same loop. Talk with the Crewhu team about connecting your CSAT results to the accounts, teams, and service work behind them.
FAQs
How recent should an industry CSAT benchmark be?
Use the newest benchmark available that matches your scoring method and feedback trigger. Check the measurement period and any changes to the question, scale, sample, or weighting. An older series still has value if it uses the same design over time. Review the benchmark after a new wave, a method change, a market shift, or a material change in your own feedback program.
Can CSAT benchmarks be compared across countries or regions?
Yes, when the scoring method, survey event, customer group, and survey period align closely. Use a local study for operating decisions. Broader, cross-country data provides orientation. If the designs differ, label the geography and explain the mismatch. The closer the market and survey setup, the stronger the basis for comparison.
How many responses make an industry benchmark useful?
The sample needs to match the decision. Check total responses, responses inside the relevant industry, how the study combined results, and how well respondents cover the customer population. A large overall sample can still contain thin industry groups. Read those details alongside your own participation trend before acting on a small gap or treating a benchmark as decisive.